
Predicting the next surgical phase is a form of procedural intent that real-time robotic surgery depends on. SurgAgents splits the task across specialised agents: a per-frame phase classifier, an instrument detector, history agents that compress what has happened into a compact temporal narrative, an LVLM phase predictor, and a confidence-gated retrieval agent that looks up similar cases when the model is unsure. On Cataract-1K it reaches 46.54% macro-F1 with GPT-4o, with latencies compatible with real-time support.
Research
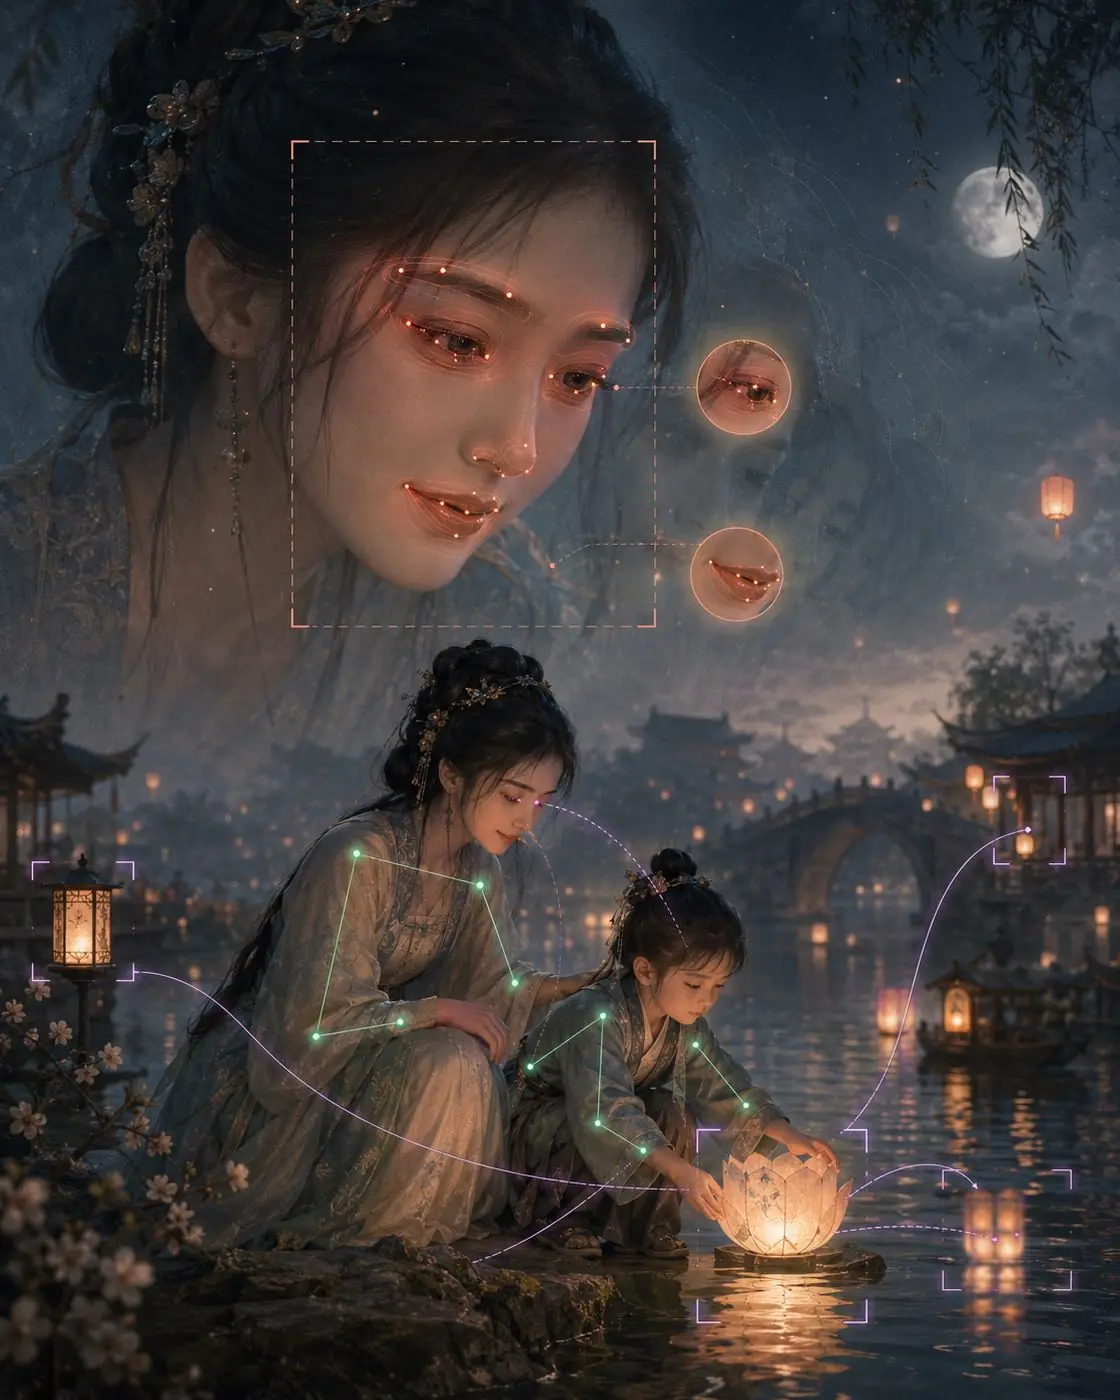
Supervised fine-tuning penalizes every reasoning token uniformly, which suppresses valid alternatives and erodes reasoning diversity. SoVTR is a reward-based framework that decomposes supervision into a Face Reward (action units, gaze, micro-expressions), a Body Reward (pose and gesture), and a Context Reward (person-object relations and scene activity), combining BERTScore attribute matching with GRPO policy optimization. It improves both accuracy and grounding quality on DFEW, FERV39k, and ExpW.

A story agent, an image agent, and a critic agent collaborate to fabricate social media posts that plausibly counter true news. Applying the framework yields over 9,000 paired multimodal news posts across science, health, and entertainment, against which 16 open- and closed-source MLLMs are benchmarked for detection. Most fall well short of human accuracy and fail critically at judging image authenticity.

Clinical text is siloed inside individual institutions, which blocks the centralized fine-tuning that medical language models normally depend on. This work pairs federated learning with parameter-efficient adaptation so each site trains locally and shares only a small set of updated parameters, never raw patient records.

LMOD+ extends our preliminary LMOD with three major enhancements: (1) nearly 50% dataset expansion; (2) broadened task coverage including binary disease diagnosis, multi-class diagnosis, severity classification; and (3) systematic evaluation of 24 state-of-the-art MLLMs.

DermEVAL is a comprehensive benchmark comprising over 11,000 images across 16 skin diseases. It facilitates evaluating state-of-the-art multimodal large language models on dermatology-specific visual question answering and medical report generation tasks.

This paper presents a representation-centric survey of skeleton-based action recognition (joints, bones, motion, derived features), introduces ANUBIS, a 102-class, multi-view (including back-view), multi-person dataset, and benchmarks existing methods.

This survey systematizes plane geometry problem solving under an encoder-decoder framework, categorizes encoders/decoders and output formats across PGPS benchmarks, and highlights key challenges (encoder-stage hallucinations, benchmark data leakage) with directions for future research.

GeoDANO is a plane geometry VLM that pairs a CLIP-trained, few-shot domain-adapted vision encoder (GeoCLIP), pretrained on synthetic diagram and caption pairs, with an LLM to robustly extract visual premises including OCR across styles, outperforming specialized and generalist baselines on MathVerse.

This study proposes a systematic data and evaluation pipeline that repurposes existing datasets to curate a dataset for the development and evaluation of large vision-language models in ophthalmology.

HandCraft is a plug-and-play framework that detects malformed hands in diffusion-generated images and restores them by aligning a parametric hand template (mask + depth) to condition ControlNet, requiring no model retraining.

This paper introduces Set-of-Vision (SoV) prompting, which enhances emotion recognition in Vision Large Language Models by using spatial visual cues like bounding boxes, numbers, and facial landmarks to precisely identify and analyze facial expressions while preserving image context.

Position-Sensing Graph Neural Networks (PSGNNs) learn to automatically select optimal anchor nodes in graphs through backpropagation rather than random selection, enabling better position-awareness.

This paper shows skeleton datasets leak sensitive attributes (≈87% gender, ≈80% re-ID) and proposes an adversarial anonymization framework that suppresses private cues while largely preserving action recognition accuracy.

Treating denoising as distribution disentanglement, the paper introduces FDN: an invertible normalizing-flow network that learns noisy-image distributions and masks noise latents to reconstruct clean images, achieving state-of-the-art AWGN/SIDD results efficiently.

The paper introduces two plug-and-play temporal modules: Discrete Cosine Encoding (injecting frequency-aware, noise-robust features) and Chronological Loss (enforcing frame order) that consistently improve diverse skeleton-based action recognizers.

The paper introduces Angular Encoding (AGE): higher-order angular features in static and velocity domains that fuse seamlessly with spatio-temporal GCN backbones to better disambiguate similar motions, yielding state-of-the-art accuracy with fewer parameters and lower inference cost.
* equal contribution † correspondence