Set-of-Vision-Text Rewards
Guiding vision large language models with verifiable face, body, and context rewards for attribute-grounded emotion recognition.
Coming SoonI am very excited to join NEC Laboratories America as a Researcher working on autonomous driving and embodied AI. I feel extremely fortunate to work with Prof. Manmohan Chandraker.
Our survey paper on plane geometry problem solving with multi-modal reasoning has been accepted by EACL Findings 2026. I'm grateful to have collaborated with an amazing team: Seunghyuk, Yang, Youngbin, Seungbeom, and Dongwoo.
Our paper on evaluating multimodal large language models for dermatology has been accepted by WACV 2026. I'm grateful to have collaborated with an amazing team: Hongjin, Weihao, Gepeng, Yang, Tom, and Nick.
I was honored to serve as an Area Chair for the ARR October 2025 cycle. I am humbly happy to make contributions to the ACL community.
I was honored to give an invited lecture at Sino-American Pharmaceutical Professionals Association (SAPA) on generative AI in healthcare.
Our paper on geometry problem solving with large vision-language models has been accepted by EMNLP Findings 2025. I'm grateful to have collaborated with an amazing team: Seunghyuk, Yang, Youngbin, Seungbeom, and Dongwoo.
LMOD was invited to present at AMIA 2025 as a podium abstract. I'm grateful to have collaborated with an amazing team: Yu, Dylan, Xuansheng, Ke, Yih-Chung, Ninghao, Xiuzhen, and Qingyu.
I was honored to give a talk on AI in healthcare at Envisioning AI at Yale, and to exchange ideas with so many thoughtful researchers afterwards.
I was honored to present our work on LMOD at NAACL 2025 in Albuquerque, and to catch up with the NLP community in person.
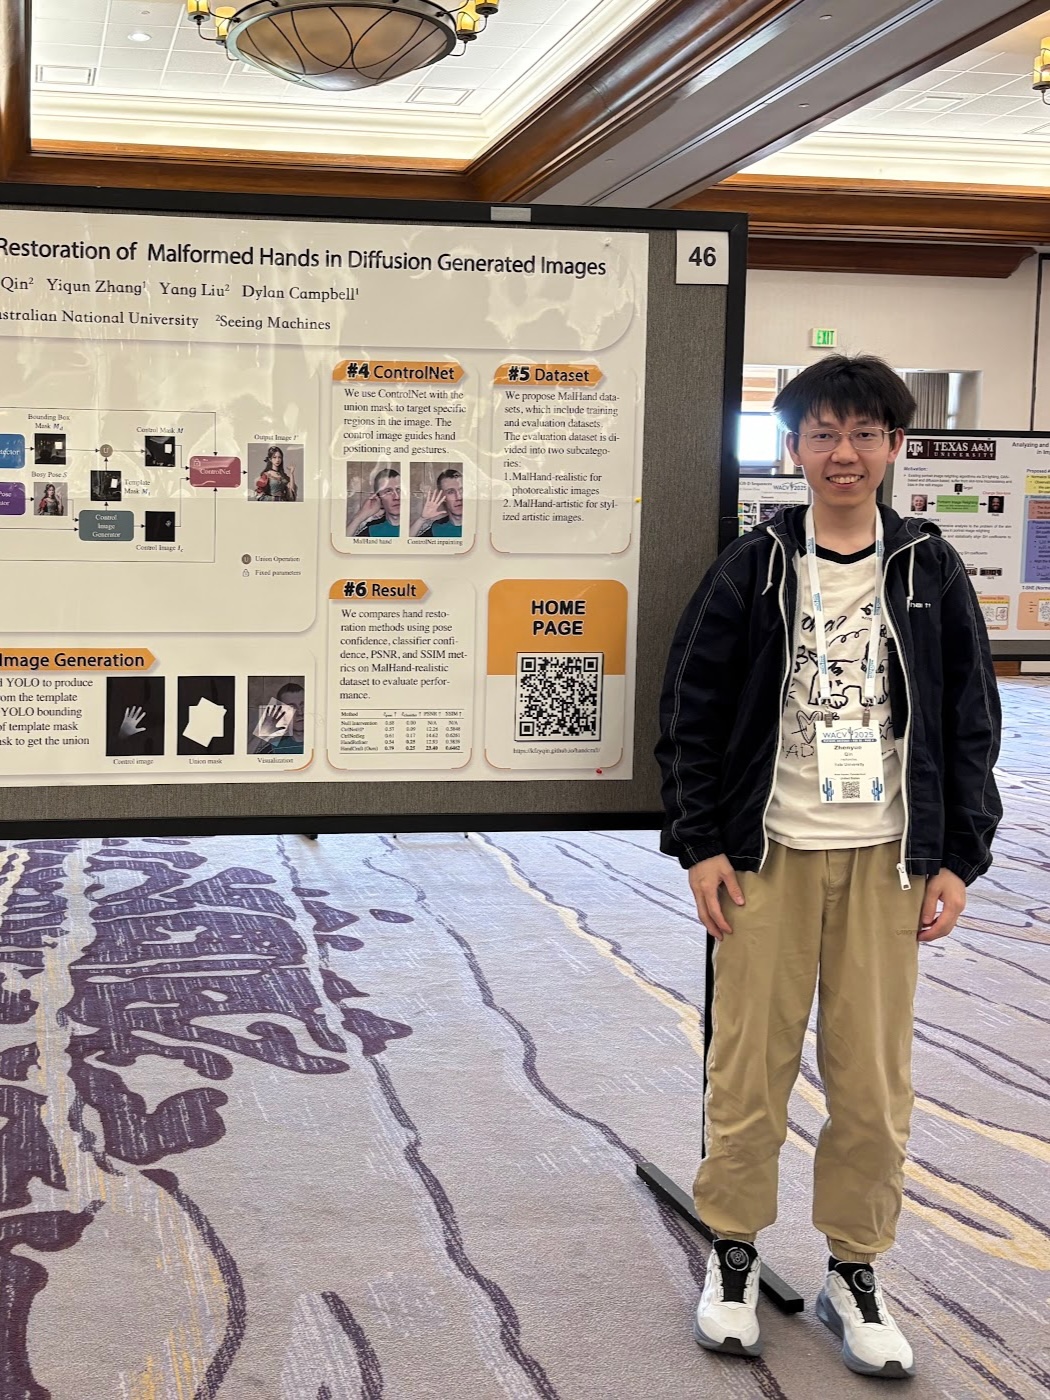
I was honored to present our work on HandCraft at WACV 2025 in Tucson, and to meet so many fellow vision researchers.
Our paper on multimodal large models and ophthalmology benchmarks has been accepted by NAACL Findings 2025. I'm grateful to have collaborated with an amazing team: Yu, Dylan, Xuansheng, Ke, Yih-Chung, Ninghao, Xiuzhen, and Qingyu.
I was honored to become an Associate PhD Supervisor at the Australian National University (ANU). I look forward to supporting students as they grow and achieve their research goals.
I was honored to serve as an Area Chair for NAACL 2025. I am humbly happy to make contributions to the ACL community.
I was honored to present our work on Set-of-Vision Prompting at EMNLP 2024 in Miami, and to learn from so many talented researchers there.
Our paper on diffusion models and generative models has been accepted by WACV 2025. I'm grateful to have collaborated with an amazing team: Yiqun, Yang, and Dylan.
Our paper on vision large language models and emotion analysis has been accepted by EMNLP Main 2024. I'm grateful to have collaborated with an amazing team: Qixuan, Zhifeng, Donghao, Wenjia, Sabrina, Tom, and Yang.